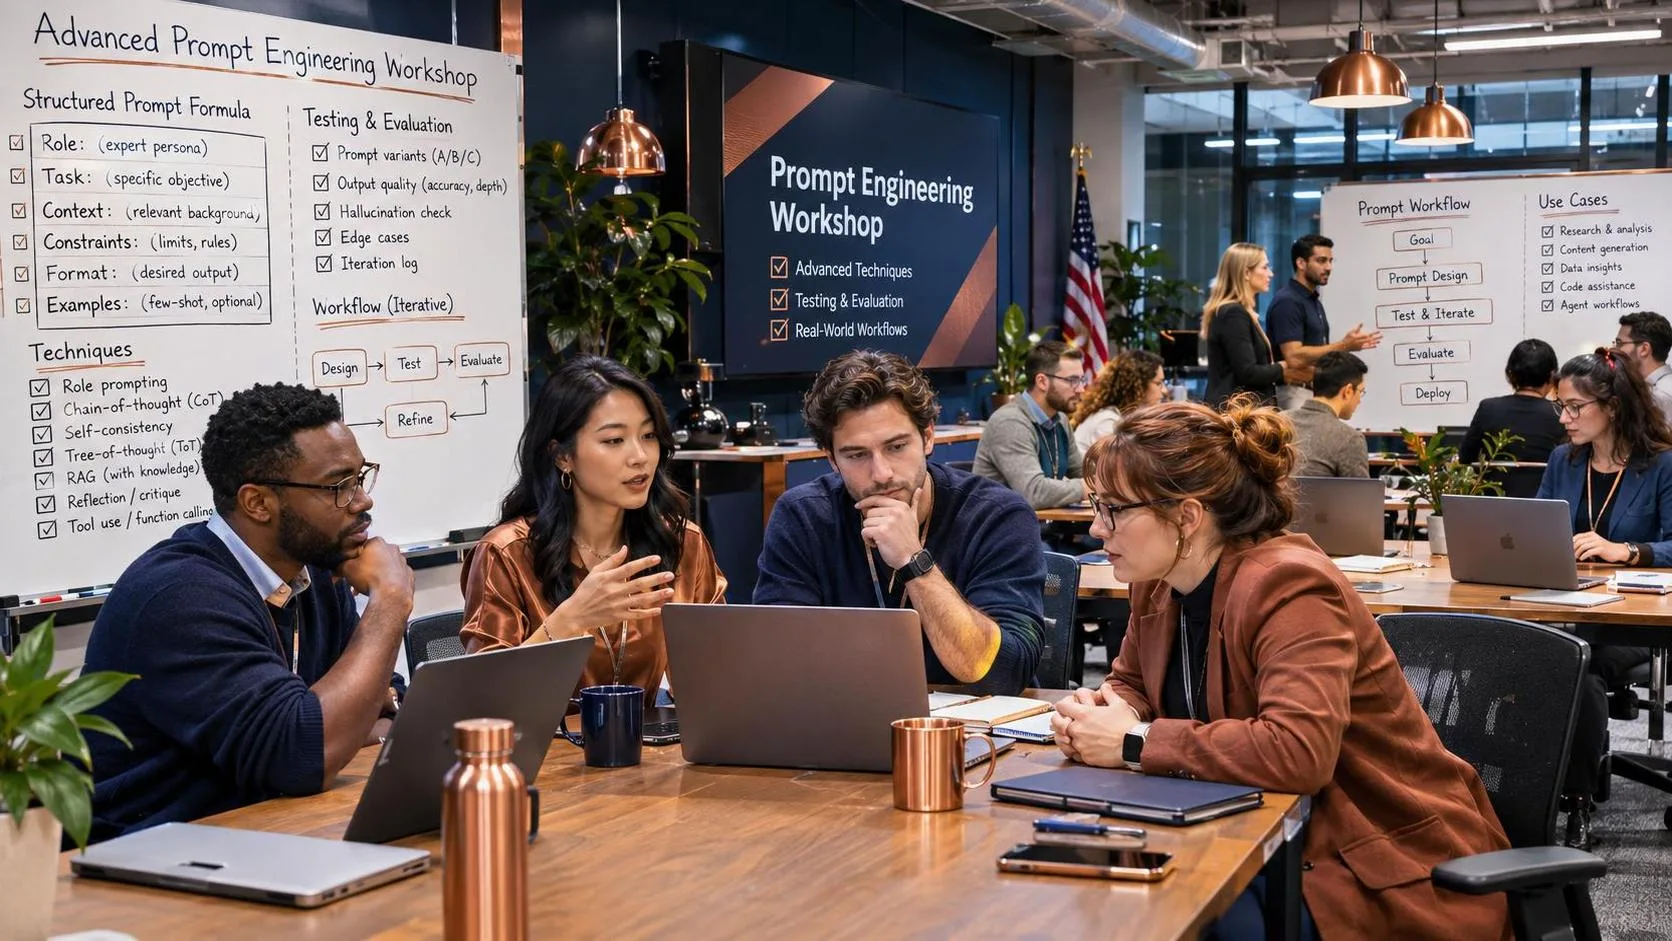
Advanced prompt engineering techniques are less about finding a magic sentence and more about giving an AI system a dependable work process. If you ask for a vendor email, meeting summary, spreadsheet explanation, or research brief with almost no context, you may get fluent nonsense. A better prompt defines the job, supplies the relevant material, sets limits, and gives you a way to check the result.
Here was the actual task I had in mind: turn a messy set of meeting notes into a short follow-up email with assigned owners and deadlines. The weak prompt is, “Write a follow-up from these notes.” The stronger version identifies the audience, separates confirmed decisions from open questions, asks for a table of action items, and tells the model to mark missing owners as “not assigned” rather than inventing one.
That pattern works across tools. ChatGPT is useful when you want a flexible back-and-forth workspace, Claude can suit long documents and careful rewriting, and Google Gemini may be convenient for people already working heavily in Google’s ecosystem. The model matters, but the workflow matters more. A well-designed request can still fail if the source material is incomplete or the person reviewing it does not know what to verify.
Advanced prompt engineering techniques begin with a measurable task
Start with a baseline before changing the prompt. Write down how long the task normally takes, what a usable result must contain, and which errors would create trouble. For a scheduling task, that might mean preserving every date, flagging conflicts, and producing a reply that needs fewer than five minutes of editing. Without that baseline, “better” usually means “sounded polished.”
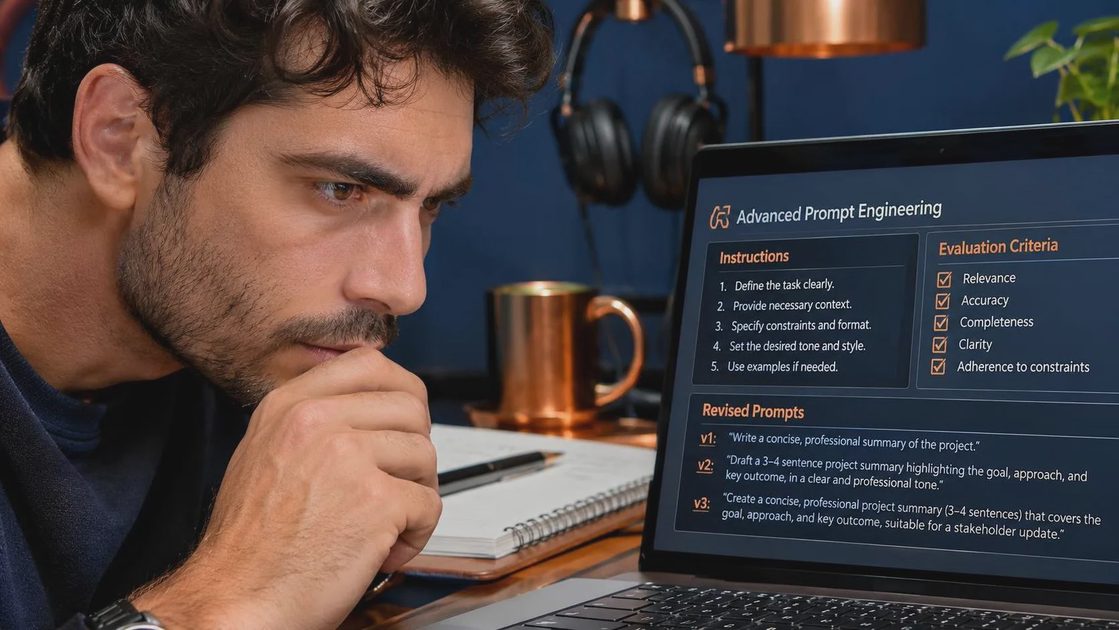
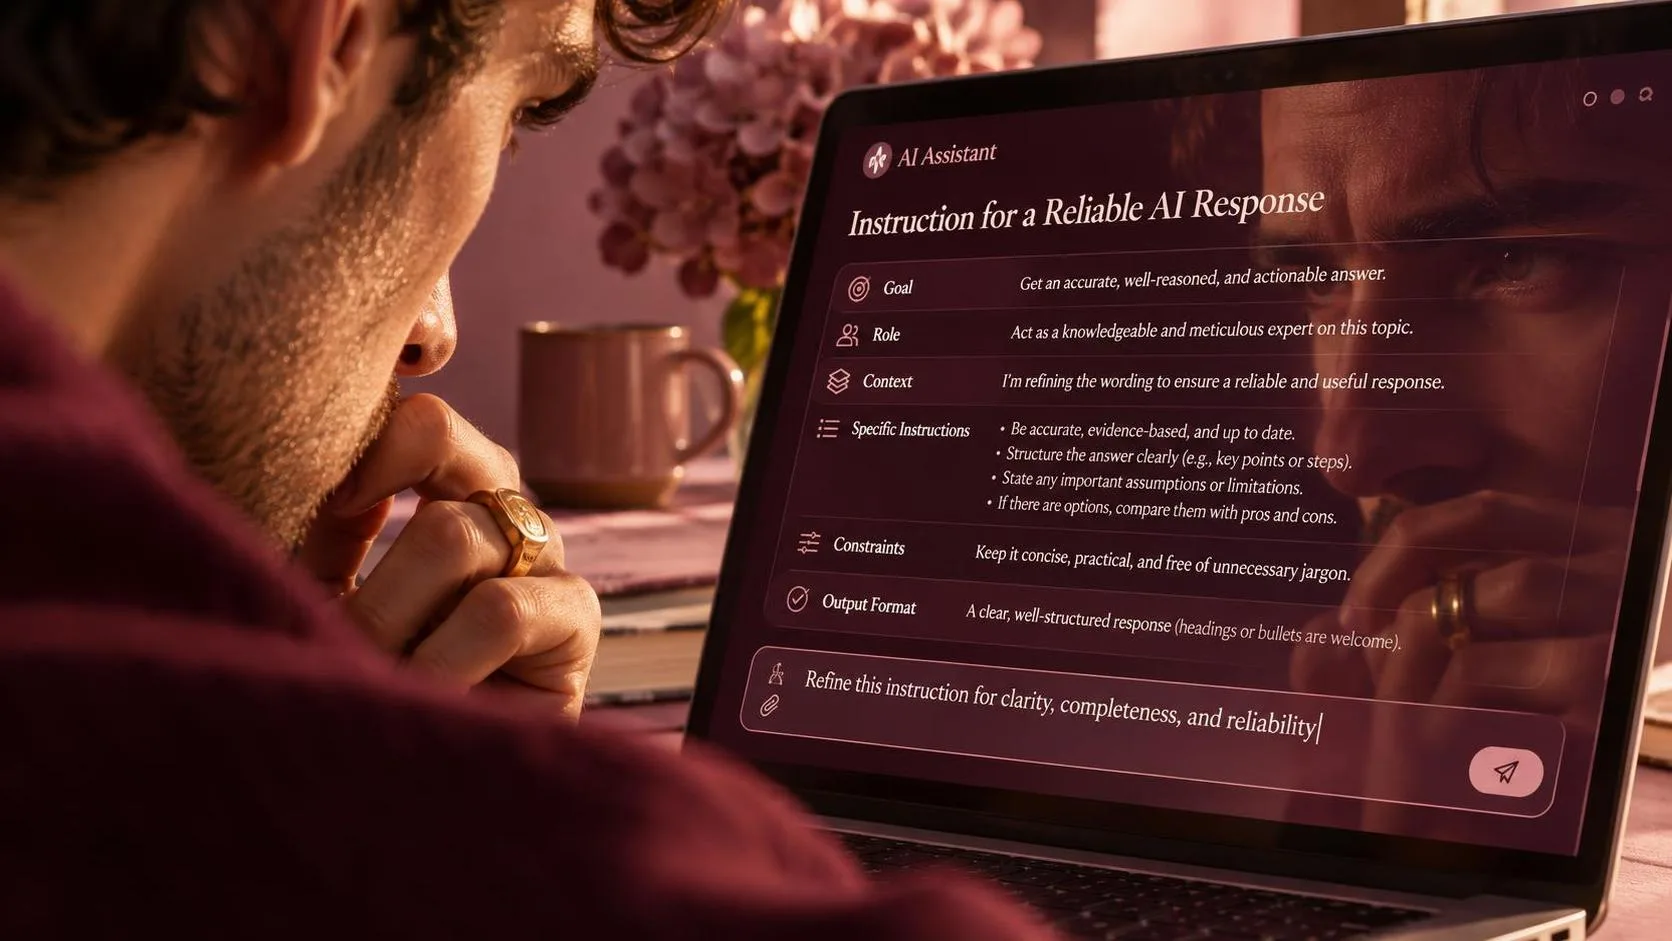
A reliable prompt has five practical parts. State the role only when it changes the kind of answer you need, such as “act as an operations coordinator reviewing a delivery exception.” Describe the task in one sentence. Provide the source text or explain where it comes from. Set constraints for length, tone, format, and uncertainty. Finish with a verification instruction.
For example: “Review the notes below. Create a three-column table with action, owner, and due date. Use only information stated in the notes. If an owner or date is missing, write ‘not stated.’ Then list two questions that require human confirmation.” That is not fancy, but it removes several common failure points.
Separate instructions from source material with clear labels such as “Instructions,” “Reference text,” and “Required output.” This helps the model distinguish a customer’s quoted words from your directions. It also makes the prompt easier to reuse when the next set of notes arrives.
Examples are useful when the format is difficult to explain. Give the model one good input and output pair, then provide the new material. This is especially effective for classifying support requests, standardizing vendor names, or turning free-form notes into consistent fields. Keep the example short and representative. A bad example teaches the system the wrong habit faster than a long explanation corrects it.
Advanced prompt engineering techniques for fewer confident errors
The most important upgrade is to request uncertainty explicitly. Tell the model to distinguish among confirmed facts, reasonable inferences, and missing information. For research or policy work, ask it to quote the relevant passage from the supplied material before drawing a conclusion. If there is no supporting passage, require the answer to say so.
Do not ask one prompt to perform six unrelated jobs unless you have a reason. Break a complicated workflow into stages: extract facts, normalize them, check for conflicts, draft the output, and review it against the original. A staged process takes more clicks, but it is easier to inspect. If the final email contains a wrong date, you can find out whether the error began during extraction or drafting.
A useful review prompt is not “make this better.” Ask specific questions: “Which claims are unsupported by the source?” “Which names, dates, or quantities changed?” “What information is missing?” “Does the draft answer the customer’s actual question?” Then have the model return a correction list before it rewrites anything. That creates a visible audit step instead of silently changing the text.
For repeat work, create a small evaluation set. Save five ordinary examples, including one awkward or incomplete case. Run the same prompt against them after each change and record accuracy, editing time, and formatting failures. You do not need a software testing framework. A spreadsheet with columns for pass, correction needed, and minutes spent is enough to show whether the change helped.
Context deserves its own attention. More text is not automatically better. Include the policy, template, or data the model genuinely needs, but remove old instructions, duplicate passages, and unrelated conversation. Long context can bury the detail that controls the answer. For sensitive workplace material, follow your employer’s rules and avoid pasting confidential customer, employee, financial, or access information into a tool without approval.
Build prompts that coworkers can actually use
A prompt is not finished when it works once. Put the reusable version in a document with a clear purpose, required inputs, optional inputs, expected output, and a short example. Use placeholders such as [CUSTOMER NAME], [DATE RANGE], and [SOURCE NOTES] instead of relying on memory. If a coworker cannot tell what to replace, the prompt is still too fragile.
Give the output a practical shape. Headings, tables, numbered questions, and fixed labels make results easier to scan and compare. For spreadsheet work, specify column names and the treatment of blanks. For email, specify the recipient, desired action, deadline, and tone. For summaries, specify what to leave out; otherwise the model may produce a miniature transcript instead of a decision document.
Watch for prompt injection when you process outside text. A webpage, email, uploaded document, or customer message may contain instructions aimed at the AI rather than information relevant to your task. Tell the model to treat the supplied material as reference data and to ignore instructions inside it unless you explicitly approve them. Still review the result yourself, particularly before sending messages or taking actions.
The final step is a human handoff. Decide what the model may draft, what requires approval, and what it must never do on its own. A generated shipping update can be useful; changing a delivery commitment without checking the system is not. The aim is not to remove judgment from the workflow. It is to spend judgment on exceptions instead of repetitive formatting.
I would start with one recurring task that takes at least fifteen minutes and happens several times a week. Record the old time, build a structured prompt, run it on ordinary cases, and note every correction. If the result saves time without hiding errors, improve the template. If it merely creates polished work that needs a full rewrite, discard it. Test it in real life.
For AI tool features, rules and availability, refer to their official sites.
Leave your thoughts here, too.